MLLMs often know the rule but pick the wrong answer. StemBind probes the same visual stem three ways: Perception (what is in the image), Rule (what pattern governs it) and Full item (which option completes it). A wrong final answer can then be traced to the sub-step that failed, on the same evidence.
Existing abstract visual reasoning (AVR) benchmarks collapse perception, rule induction, and answer selection into a single right-or-wrong signal, so they cannot tell why a model failed. We introduce StemBind, a shared-stem diagnostic benchmark that probes the same visual stem with three aligned questions (Perception, Rule, and Full), so a final-answer error can be attributed to a specific sub-step on the same evidence. StemBind contains 2,298 curated knowledge-light stems across nine auditable visual operations, totaling 19,533 P/R/F tasks, with each full item annotated by Sternberg's four reasoning stages (S1 Encode, S2 Infer, S3 Map, S4 Apply).
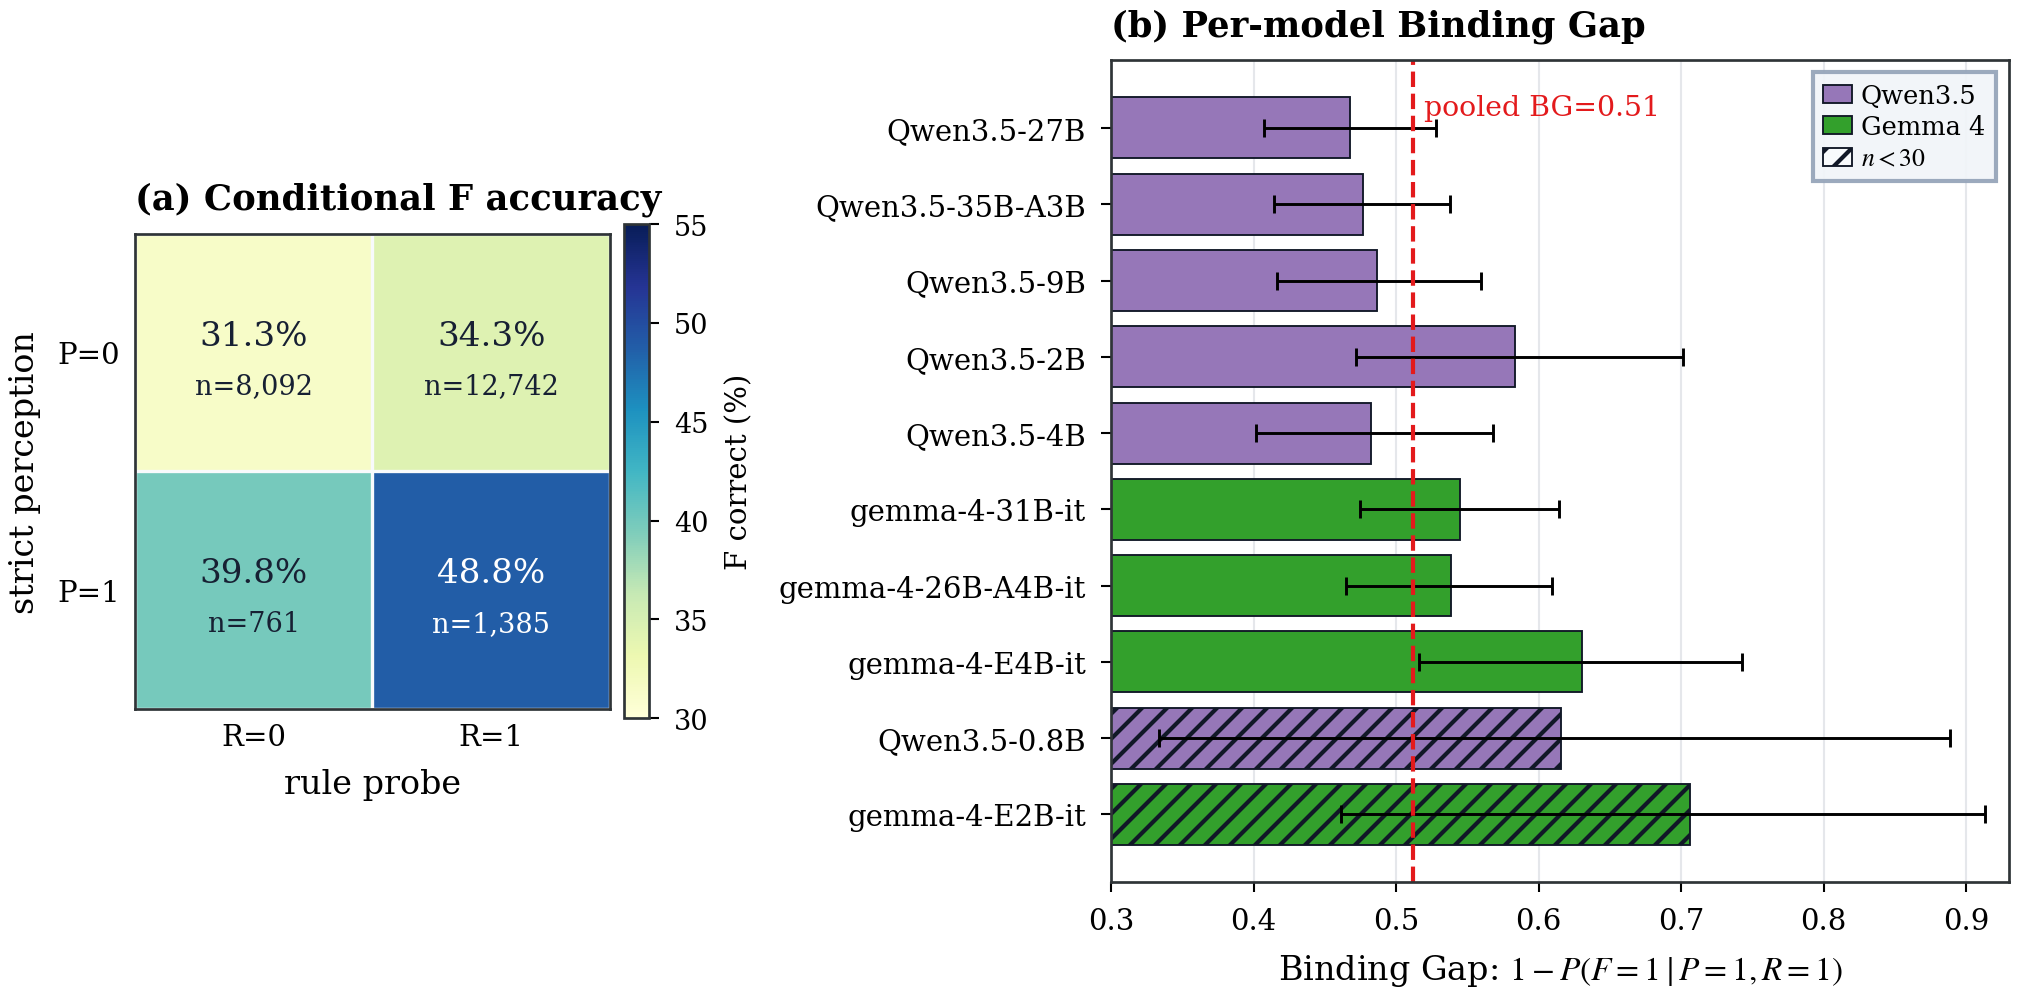
Evaluating 24 frontier MLLM configurations yields four findings: (i) rule accuracy exceeds full-item accuracy on 22 of 24 models, so most failures happen after the rule is identified; (ii) even when perception and rule are both correct on the same stem, models still answer Full incorrectly 51.2% of the time; (iii) process diagnostics and Stage-wise Stimulus Augmentation localize the dominant failure to S3 rule-to-instance mapping; and (iv) neither scaling up model size nor enabling explicit thinking reliably closes the gap. StemBind reframes AVR evaluation from final-answer ranking to locating where abstract visual reasoning breaks down.
All 24 models on the full benchmark. Click a column to sort. R − F is the rule-to-full drop.
| # | Model | Type | P | R | F | R − F |
|---|---|---|---|---|---|---|
| 1 | Qwen3.5-Plus | Proprietary | 71.9 | 44.7 | 42.2 | +2.5 |
| 2 | Qwen3.5-27B | Open | 72.9 | 65.4 | 41.3 | +24.1 |
| 3 | Qwen3.5-35B-A3B | Open | 72.6 | 59.8 | 39.3 | +20.5 |
| 4 | Qwen3.5-9B | Open | 68.9 | 60.1 | 37.4 | +22.7 |
| 5 | Kimi-K2.5 | Open | 65.9 | 58.4 | 36.8 | +21.6 |
| 6 | Qwen3.5-2B | Open | 61.4 | 60.5 | 35.9 | +24.6 |
| 7 | Gemini-3.1-Pro | Proprietary | 58.7 | 24.3 | 35.9 | -11.6 |
| 8 | GLM-4.5V | Open | 63.4 | 54.1 | 34.6 | +19.5 |
| 9 | Qwen3.5-4B | Open | 66.5 | 56.7 | 33.8 | +22.9 |
| 10 | Qwen3.5-122B-A10B | Open | 55.7 | 29.6 | 33.8 | -4.2 |
| 11 | Gemma-4-31B-it | Open | 67.0 | 67.5 | 33.1 | +34.4 |
| 12 | Gemma-4-26B-A4B-it | Open | 71.7 | 65.4 | 33.0 | +32.4 |
| 13 | GPT-5.4 | Proprietary | 61.2 | 60.1 | 31.8 | +28.3 |
| 14 | Claude-Opus-4.7 | Proprietary | 60.8 | 56.2 | 30.7 | +25.5 |
| 15 | Gemma-4-E4B-it | Open | 66.0 | 55.0 | 30.6 | +24.4 |
| 16 | Qwen3.5-0.8B | Open | 41.5 | 48.7 | 30.2 | +18.5 |
| 17 | InternVL3.5-30B-A3B | Open | 45.1 | 32.9 | 28.9 | +4.0 |
| 18 | Gemma-4-E2B-it | Open | 58.9 | 43.0 | 28.6 | +14.4 |
| 19 | Grok-4.2-beta | Proprietary | 49.3 | 31.3 | 28.1 | +3.2 |
| 20 | InternVL3.5-14B | Open | 43.2 | 30.7 | 28.1 | +2.6 |
| 21 | InternVL3.5-8B | Open | 39.5 | 33.6 | 26.7 | +6.9 |
| 22 | InternVL3.5-4B | Open | 36.8 | 27.9 | 24.8 | +3.1 |
| 23 | InternVL3.5-2B | Open | 34.9 | 29.4 | 23.1 | +6.3 |
| 24 | InternVL3.5-1B | Open | 30.6 | 24.8 | 20.7 | +4.1 |
Per-operation scores and thinking-mode deltas are in Table 2 of the paper. To evaluate a new model, see the code repository.
Rule accuracy exceeds full-item accuracy on 22 of 24 models, often by 20–34 points. Even on the strict subset where perception and rule are both correct on the same stem, models still miss the full item 51.2% of the time. The failure is behavioral rule-to-instance binding, not a missing rule.


Stage-wise judging and Stage-wise Stimulus Augmentation (SSA) both point to S3 rule-to-instance mapping: S3 is the weakest stage on every full-split row, and the largest SSA gain appears when S3 alignment is injected. This is a behavioral localization, not a mechanistic claim.

Within-family scaling shifts perception and rule far more than full-item accuracy. Qwen3.5 dense models peak before the MoE variants and the largest MoE variant collapses on rule, while Gemma 4 and InternVL3.5 improve on Full yet keep the R–F chasm.

Across paired direct/thinking rows, explicit thinking lifts perception on nine of ten rows but lowers both rule and full-item accuracy on every row. Longer traces help local descriptions but break the slot-level correspondence the full item requires.

@inproceedings{he2026stembind,
title = {StemBind: When MLLMs Get Lost Between Rules and Instances in Abstract Visual Reasoning},
author = {He, Xixiang and Wu, Baiqi and Li, Xingming and Cheng, Ao and Sun, Qiyao and Ji, Xuanyu and Hu, Qingyong},
booktitle = {Advances in Neural Information Processing Systems (NeurIPS)},
year = {2026}
}